AhoosAI Studio 3.1, PML-sRUN out under MIT, and the Terminal CLI
Three releases in one day: the offline studio twice as fast on a small graphics card and working with any model you have a key for; PML-sRUN, the method behind it, open on GitHub with a control panel; and the Terminal CLI, with the online studio's abilities in a terminal and an agent of its own.
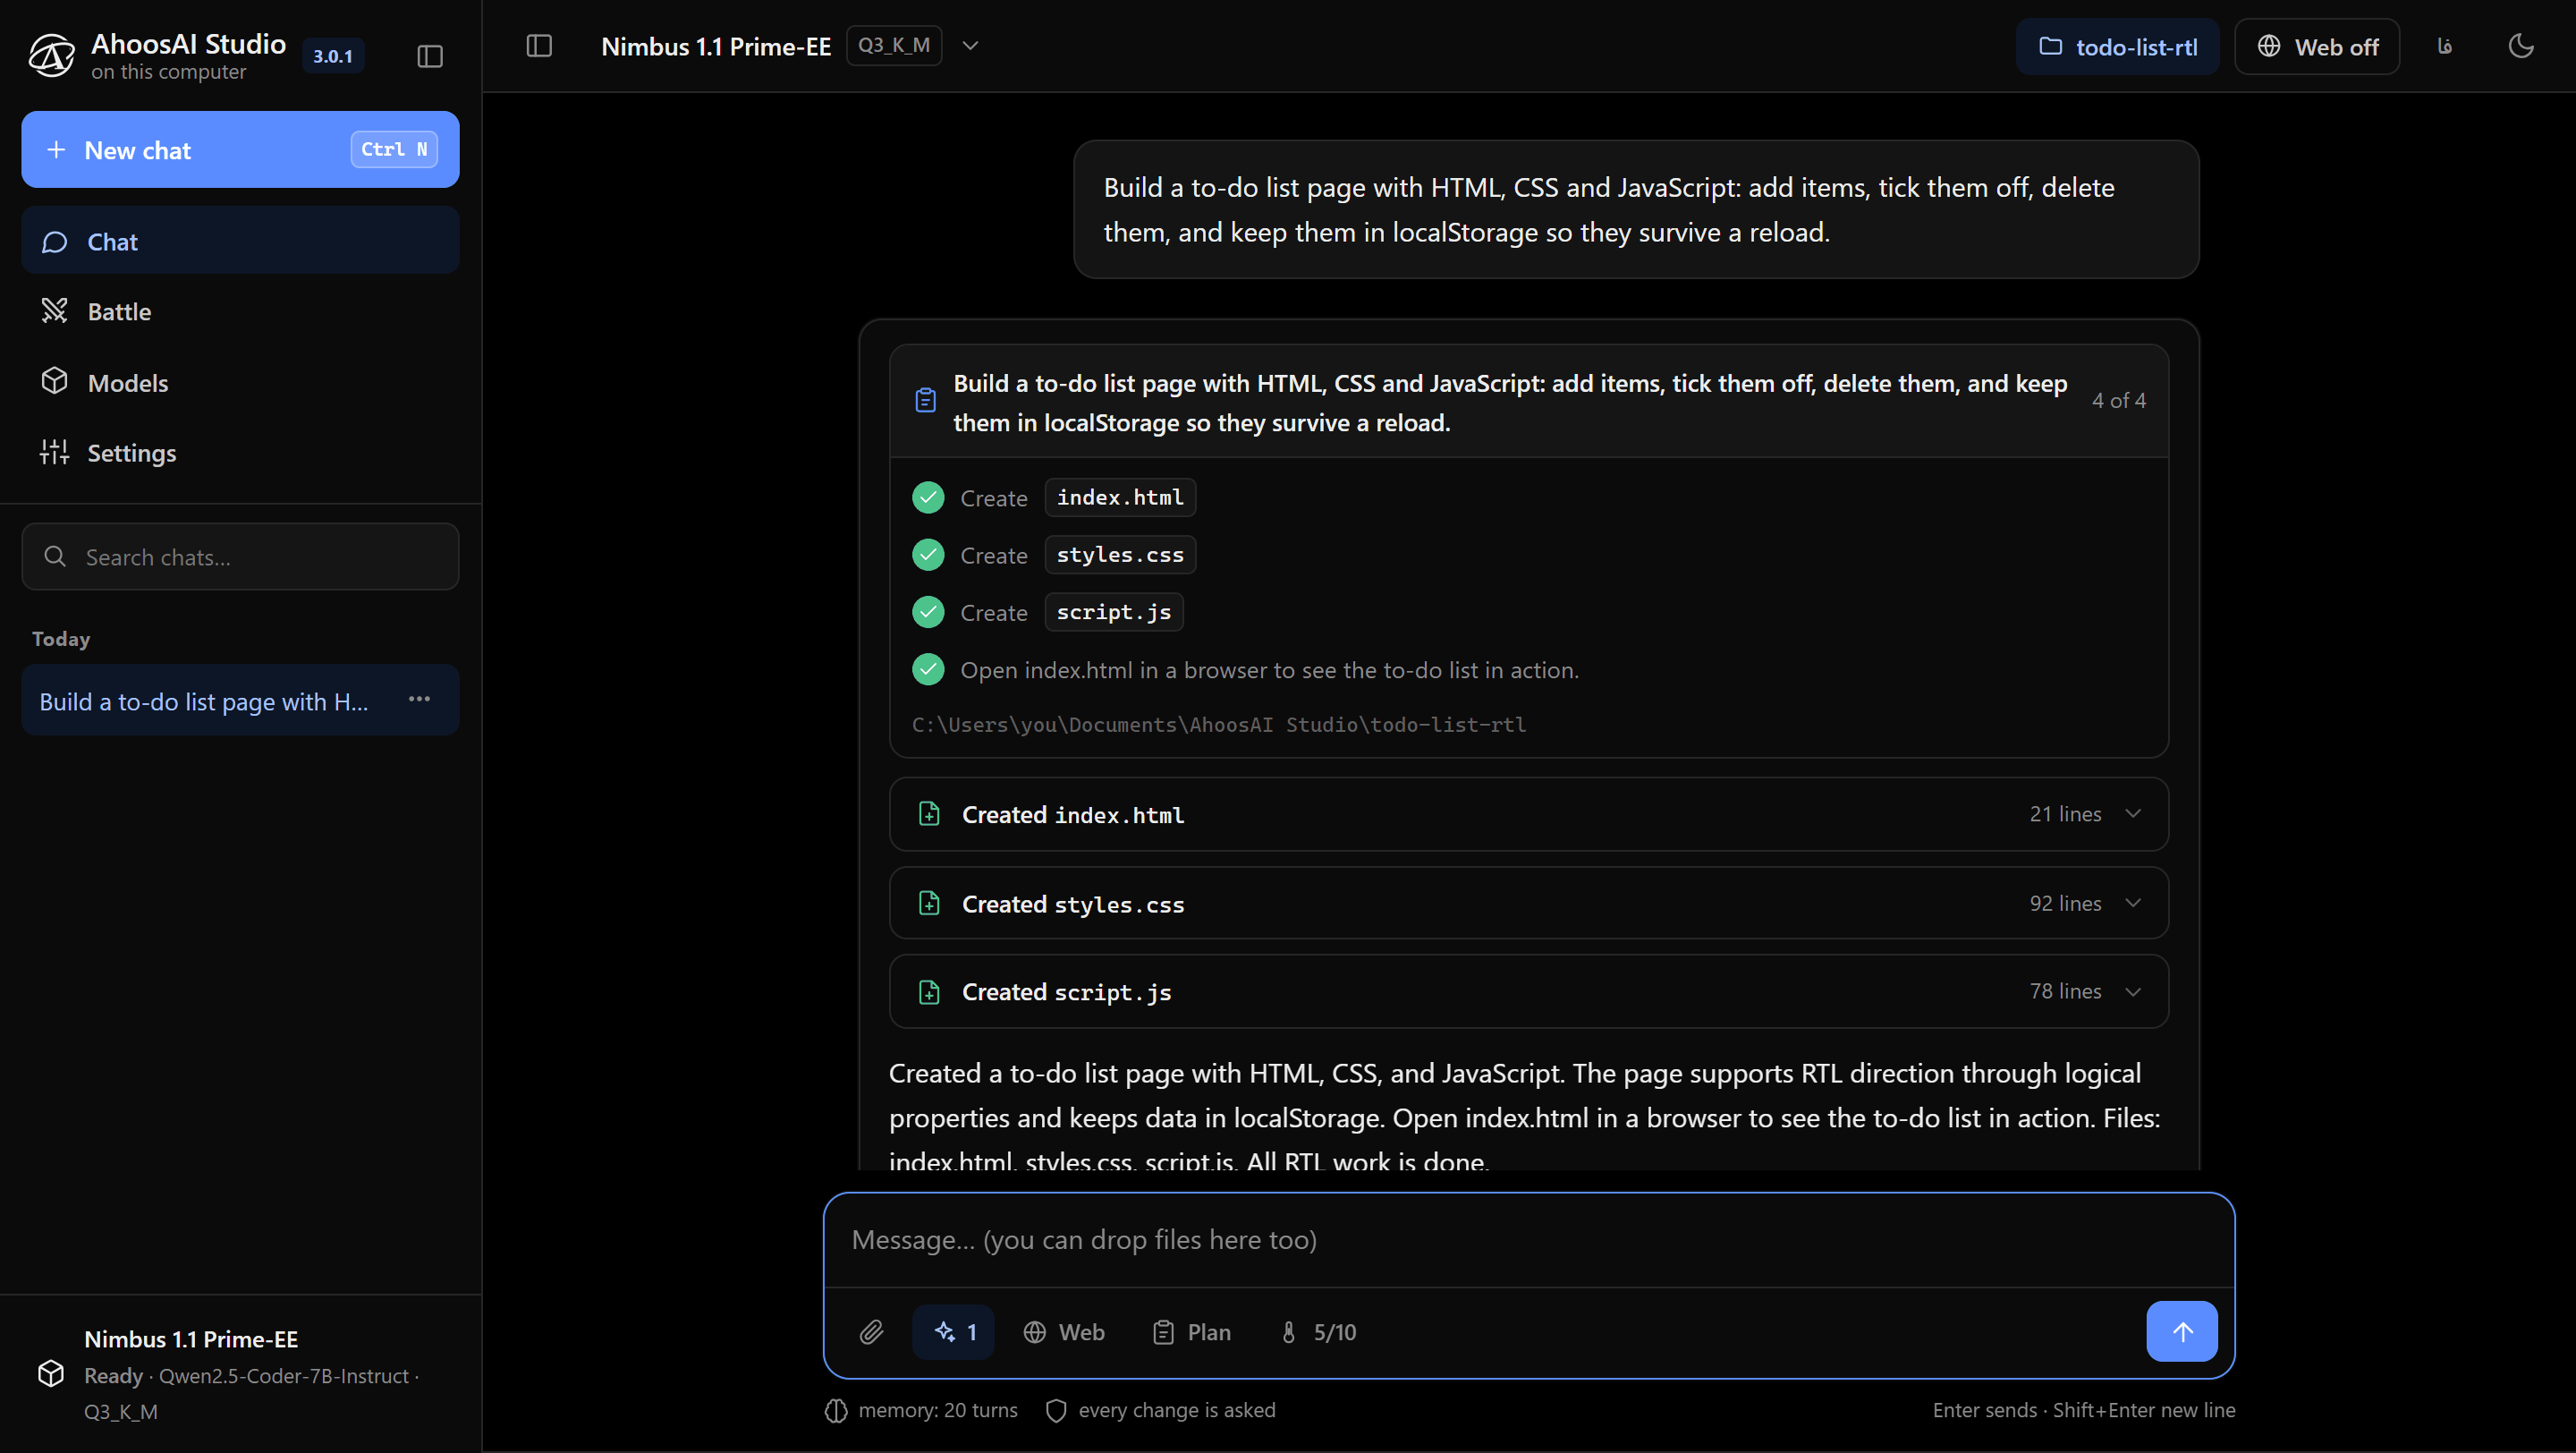
AhoosAI Studio 3.1
PML-sRUN places the model. A model that does not fit on your graphics card is split the way that runs it fastest on your machine: on a laptop with a 4 GB GTX 1050 Ti and a 7B coding model, 7.4 tokens a second against 3.6 for llama.cpp's own placement, and 10.2 on code edits. On a Mac the model goes on Apple's own GPU.
Online models, with every tool. With an API key -- AhoosAI's Nimbus 2 Apex, OpenAI, OpenRouter, Groq, Gemini, DeepSeek or any OpenAI-compatible service -- an online model plans, writes and edits files, runs commands, searches the web and checks its work exactly as a local one does, and every change can be undone.
Answers that show more: tables read across or down, charts drawn from the model's numbers, sections, steps, notes and warnings. And installers: a Windows installer that needs no administrator, and a .deb for Debian and Ubuntu.
PML-sRUN, open
PML-sRUN made by AhoosAI is on GitHub under the MIT license. It reads a model's file and your machine, decides where each piece goes -- the graphics card, the computer's memory or the disk -- and why, then measures the plan and its neighbours and keeps the fastest. A control panel in the browser sets up llama.cpp for your machine, plans, measures and runs the model; Python 3.10 is all it needs. Against Ollama on the same file: 7.4 tokens a second against 4.9.
The online engine runs it too: on the T4 that serves Nimbus 2 Apex, PML-sRUN 0.3.1 guesses ahead with a small draft model and n-gram drafts together, and the reasoning went from 13.3 to 38.4 tokens a second.
Terminal CLI
Terminal CLI made by AhoosAI is the terminal client, rewritten for today's API: one key from the platform page and you have Nimbus 2 Apex's reasoning as it comes, its two dials, web search, plan mode, files and pictures, chats kept and reopened, the context meter and compaction, custom instructions, and answers drawn for a terminal -- tables with borders, charts as bars, code and notes. Agent mode does what the online studio cannot: the model reads, writes and edits the files in the folder you are in and runs commands, each change shown with its diff and asked first.
Install it with one line -- irm https://ahoos-ai.site/downloads/cli/install.ps1 | iex on
Windows, curl -fsSL https://ahoos-ai.site/downloads/cli/install.sh | sh on Linux and macOS --
or download the program, or the source, which runs with Python alone.
PML-sRUN made by AhoosAI · Terminal CLI made by AhoosAI · MIT License.